SpeechLLM ASR: English speech recognition powered by Villanova-2B
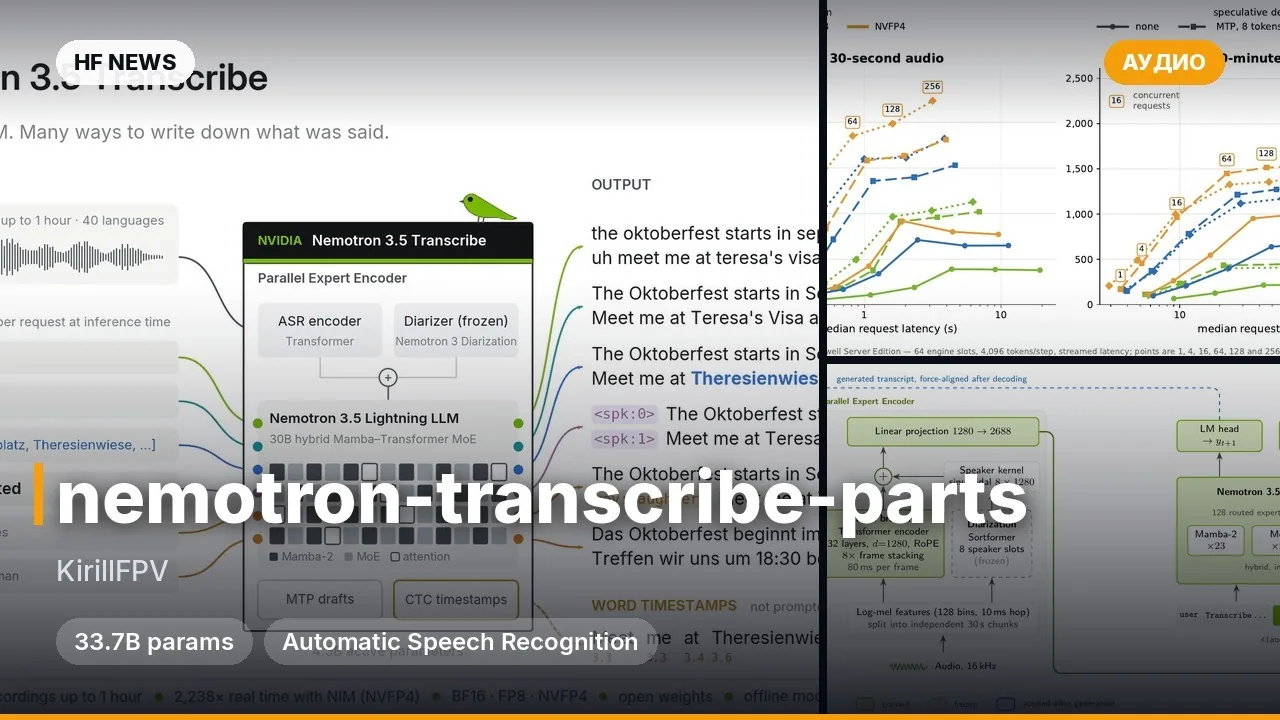
This is a multimodal speech language model (SpeechLLM) for automatic English speech recognition, built on the SLAM-LLM framework. The architecture combines a frozen FAMA encoder, a linear projector, and the Villanova-2B model with LoRA (a lightweight adapter for the base model).