#audio
269 posts
mg-voca: Malagasy mobile TTS
The mg-voca model handles text-to-speech tasks for the Malagasy language, producing 24 kHz audio. It supports two voices (female and male) and weighs only 21 MB in ONNX format, enabling local operation on a CPU, in a browser, or on a smartphone without an internet connection.
AzurLane GPT-SoVITS V5dev: 902 character voices for voice generation
A set of weights for the popular GPT-SoVITS V5dev speech synthesis system, trained on Japanese and Chinese voice lines from the game Azur Lane. The model covers 902 ship characters and lets you generate speech in Russian, Chinese, or Japanese using a short audio clip (3 to 10 seconds) as a…
AzurLane GPT-SoVITS v2ProPlus: 902 Character Voice Pack
This set of weights for GPT-SoVITS (a voice cloning and speech synthesis system) is trained to voice 902 ships and TB assistants from Azur Lane in Japanese and Chinese. A total of 933 voice presets are available, including alternative versions and different localization options.
Geode ACE-Step 1.5 turbo: running music generation on smartphones
This model is a converted version of the fast ACE-Step 1.5 turbo music model (created by ACE Studio and StepFun), adapted to run directly on mobile phones via the Geode Android app.
SpeechLLM ASR: English speech recognition powered by Villanova-2B
This is a multimodal speech language model (SpeechLLM) for automatic English speech recognition, built on the SLAM-LLM framework. The architecture combines a frozen FAMA encoder, a linear projector, and the Villanova-2B model with LoRA (a lightweight adapter for the base model).
vits-ru-mms-graphemes: A Russian text-to-speech model in ONNX format
This model is a variant of Meta's VITS architecture, based on the facebook/mms-tts-rus project and repackaged to work with the phoonnx ONNX library. It takes Russian text as input and generates high-quality audio (a WAV file).
Pocket TTS Core ML with timestamps: Speech synthesis with precise word-level timing
This model is a conversion of Kyutai's Pocket TTS speech engine into the Core ML format for running on Apple devices. The key feature of this version is the added export of word-level timestamps (the exact pronunciation time of each word) directly during speech generation, enabled by the attention…
NeyroLearn
@neyrolearn
New models from Hugging Face every morning: video, images, LoRAs and LLMs with examples and links.
- Posts
- 269
- Tags
- 59
Trending
Most liked on Hugging Face this week
- 1Add Micro Details
Images · 8.4K
 18+
- 2MiniMax-H3
Video · 7.2K
- 3Flat Color - Style
Images · 6.2K
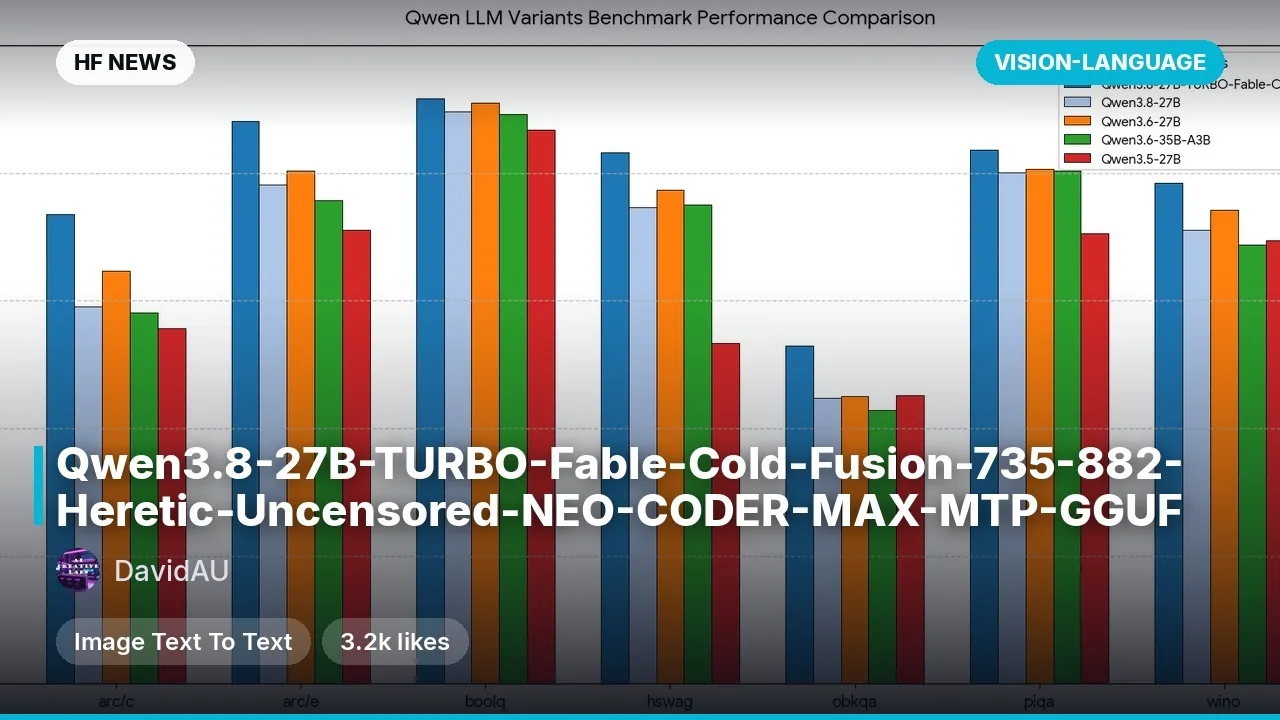
- 4Qwen3.8-27B-TURBO-Fable-Cold-Fusion-735-882-Heretic-Uncensored-NEO-CODER-MAX-MTP-GGUF
Computer vision · 3.5K
- 580s Fantasy Movie
Images · 3.1K
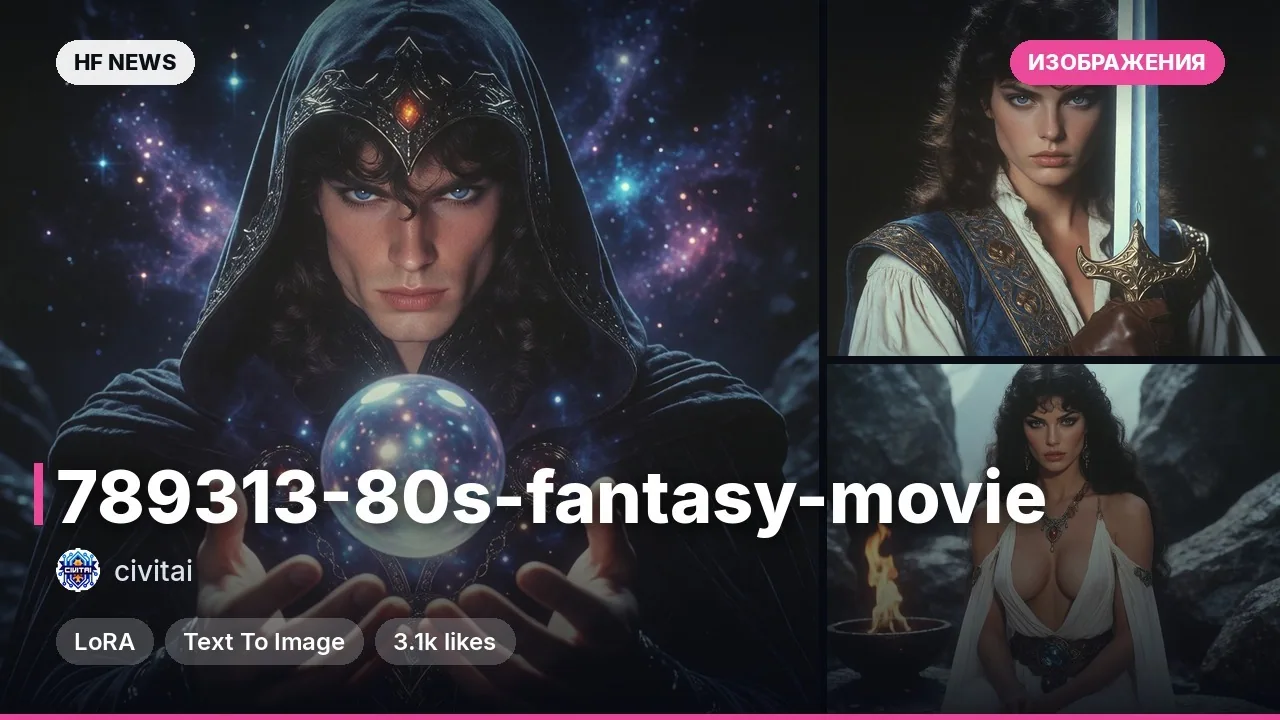 18+
Popular tags
- #finetune1740
- #LLM1333
- #models1286
- #LoRA1067
- #Qwen923
- #images583
- #txt2img480
- #robotics467
- #VLM346
- #audio269
- #NSFW206
- #Krea192
- #video181
- #MiniMax_H3166
- #ComfyUI155
- #Gemma139
- #turbo127
- #MOSS_Image123
- #ASR107
- #TTS98