New VLMs
Multimodal models that understand text and images.
GeoReader-Qwen2.5-VL-3B-MindCube: A Vision-Language Model for Geospatial Analysis
The GeoReader-Qwen2.5-VL-3B-MindCube model is a full checkpoint (set of weights) based on Qwen2.5-VL-3B-Instruct, fine-tuned for spatial perception and geometry tasks. The architecture combines a vision-language model (VLM), a frozen geometric reader, an adapter, and a gate.
openT2L-MiniCPM-V-4.7-1B-docs - Zero-training LoRA adapter generator for documents
This hypernetwork (a neural network that generates weights for another model) by author ASHu2 solves the problem of slow fine-tuning for new document layouts. You provide just 4 examples of unfamiliar page types with the required JSON output, and in a single forward pass it creates a ready-to-use…
Qwen3.8-27B-super-adapter GGUF
A single local model for three coding agents
Inkling-2-Mini Uncensored LoRA
removing restrictions from a compact multimodal model
gemma-4-31B-it-The-DECKARD-HERETIC-UNCENSORED-Thinking
an uncensored version with a reasoning mode
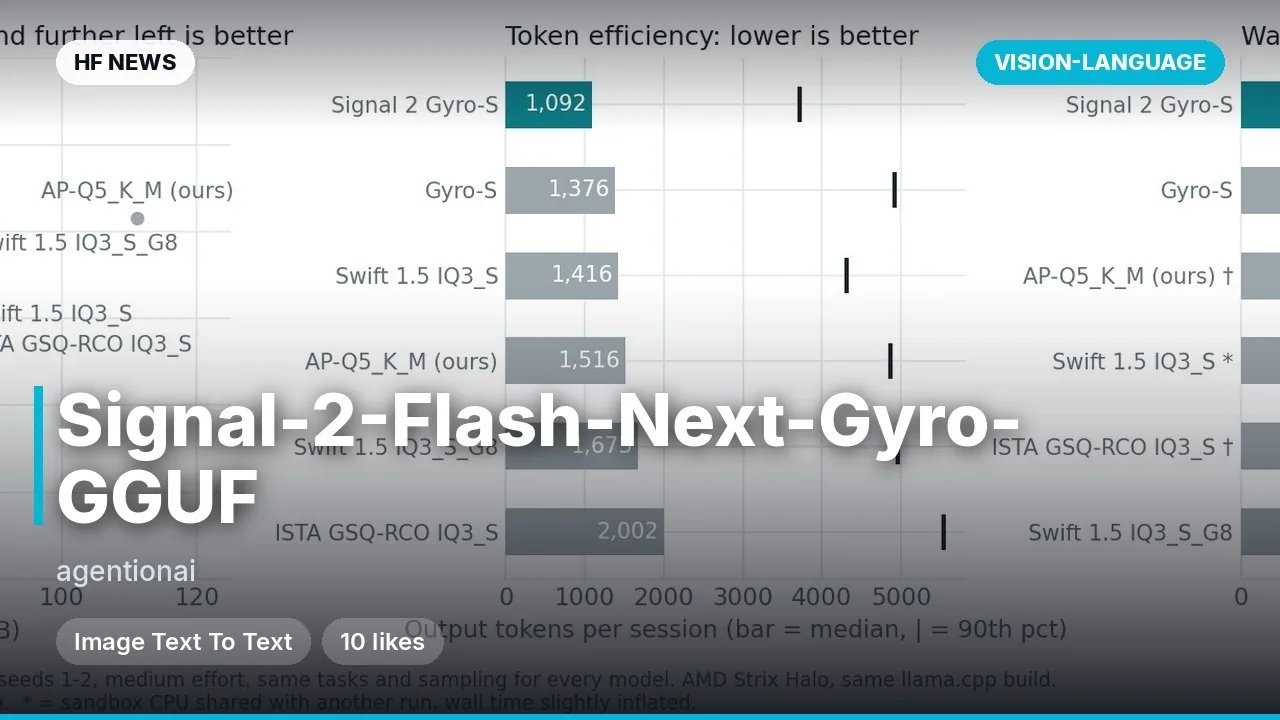
Ltx-2.3 22b Ic-Lora Motion Track Control
precise trajectory video motion control
MiniMax-H3-Prompt-Rewriter: Quantized Version of the Multimodal Model
The model is a quantized (compressed) version of lightx2v/MiniMax-H3-Prompt-Rewriter-Qwen3.8-27B-Ref2VA created using the llm-compressor library. The primary task of this LLM (large language model) is enhancing and rewriting prompts (text queries) for generative pipelines, taking visual data into…
Molmo 7B-D: Open multimodal model from the Allen Institute for AI
Molmo 7B-D is an open vision-language model developed by the Allen Institute for AI, built on the Qwen2-7B language model and the OpenAI CLIP visual backend. The model was trained on a carefully curated PixMo dataset of 1 million image and text pairs.
andreafanfani/gemma-4-12B-it-uncensored
an uncensored version of the multimodal model
Escriba-OCR-1B: Handwritten text recognition preserving errors
The model specializes in digitizing handwritten student essays in Brazilian Portuguese. Unlike universal OCR systems and VLMs, it does not correct the author's errors, instead transcribing them accurately line by line.
NeyroLearn
@neyrolearn
New models from Hugging Face every morning: video, images, LoRAs and LLMs with examples and links.
- Posts
- 346
- Tags
- 59
Trending
Most liked on Hugging Face this week
- 1Add Micro Details
Images · 8.4K
 18+
- 2MiniMax-H3
Video · 7.2K
- 3Flat Color - Style
Images · 6.2K
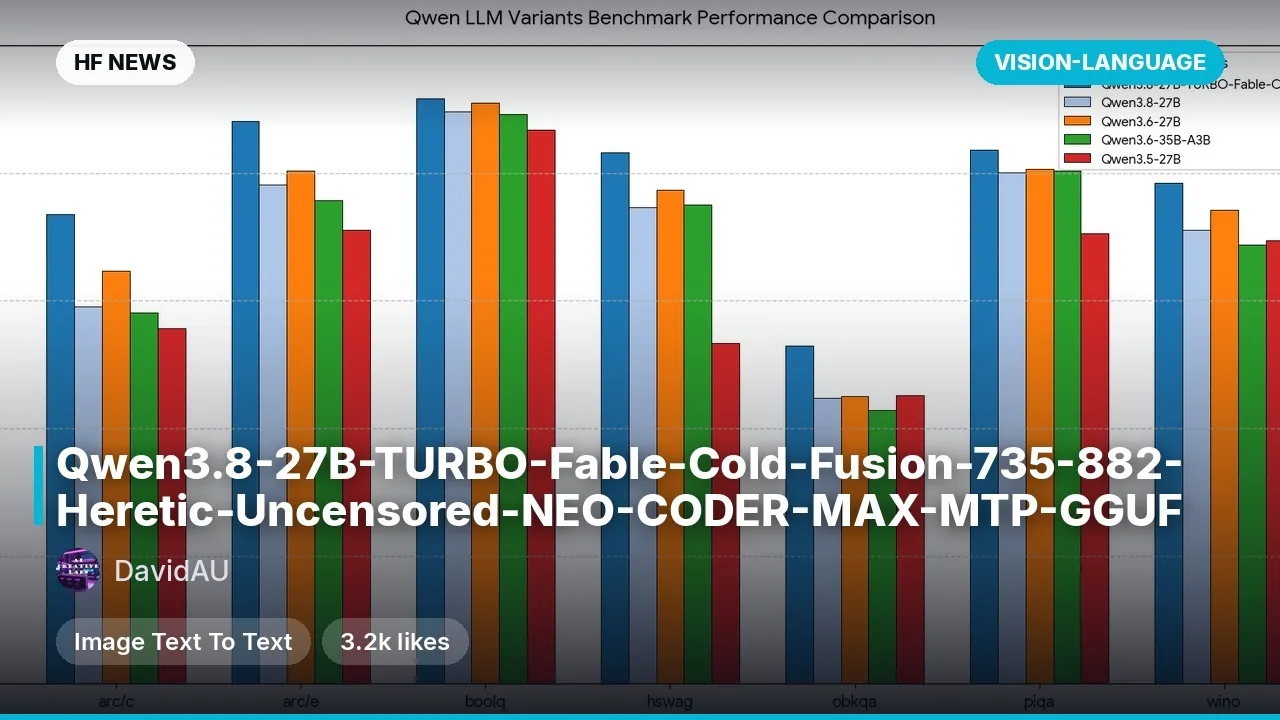
- 4Qwen3.8-27B-TURBO-Fable-Cold-Fusion-735-882-Heretic-Uncensored-NEO-CODER-MAX-MTP-GGUF
Computer vision · 3.5K
- 580s Fantasy Movie
Images · 3.1K
 18+
Popular tags
- #finetune1740
- #LLM1333
- #models1286
- #LoRA1067
- #Qwen923
- #images583
- #txt2img480
- #robotics467
- #VLM346
- #audio269
- #NSFW206
- #Krea192
- #video181
- #MiniMax_H3166
- #ComfyUI155
- #Gemma139
- #turbo127
- #MOSS_Image123
- #ASR107
- #TTS98
About the VLM tag
VLMs are language models with vision: show them a picture, a screenshot or a document and ask a question. Here are new VLMs and their fine-tunes from Hugging Face.
Looking for a specific model? Paste its name or Hugging Face link into search, or describe your task to the assistant on the home page.