New VLMs · page 4
Multimodal models that understand text and images.
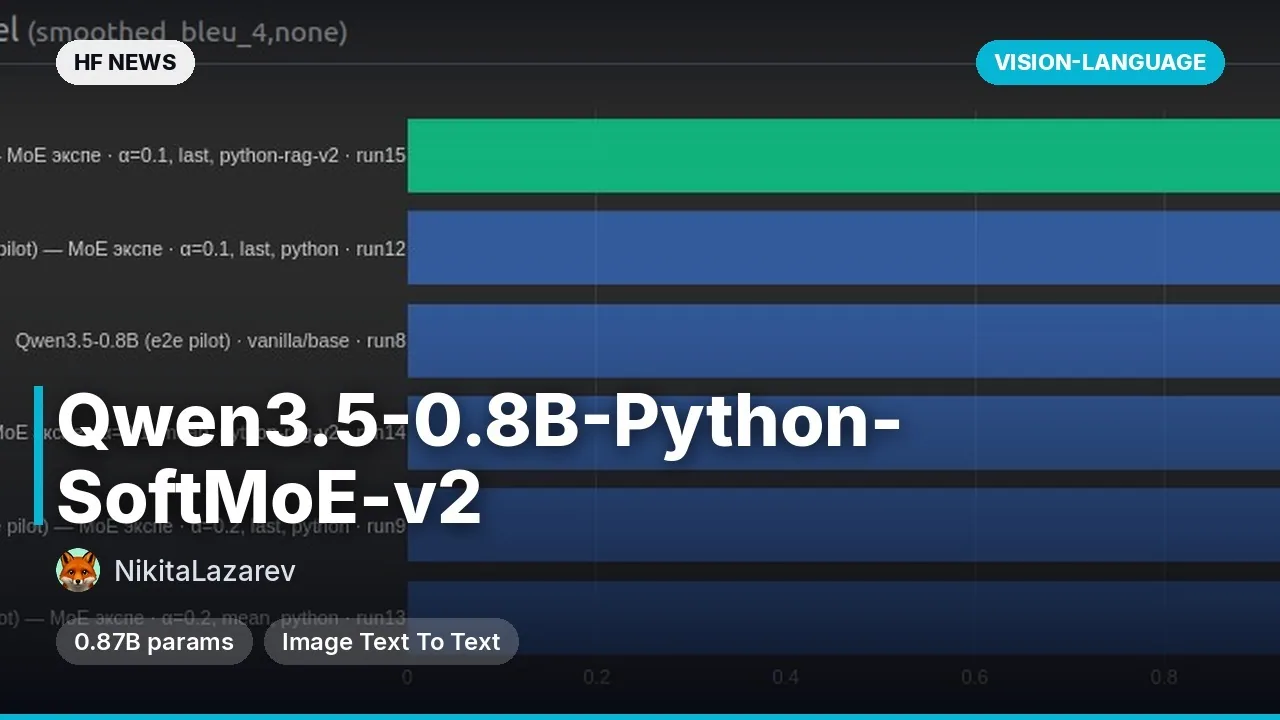
Qwen3.5-0.8B-Python-SoftMoE-v2
a soft MoE Python expert without fine-tuning
Qwen3.6-35B-A3B-REAP25
lightweight Qwen3.6 variant with pruned MoE experts
amaara-decide-vision
a vision model for fast multiple-choice selection
Qwen3.5-9B CyberSecurity (Abliterated)
a cybersecurity model without unnecessary refusals
qwen3.5-2b-receipt-invoice-extract-lora
receipt and invoice data extraction to JSON
TinyForge-Vision-222M
a compact multimodal model for visual question answering
NeyroLearn
@neyrolearn
New models from Hugging Face every morning: video, images, LoRAs and LLMs with examples and links.
- Posts
- 349
- Tags
- 59
Trending
Most liked on Hugging Face this week
- 1Add Micro Details
Images · 8.4K
 18+
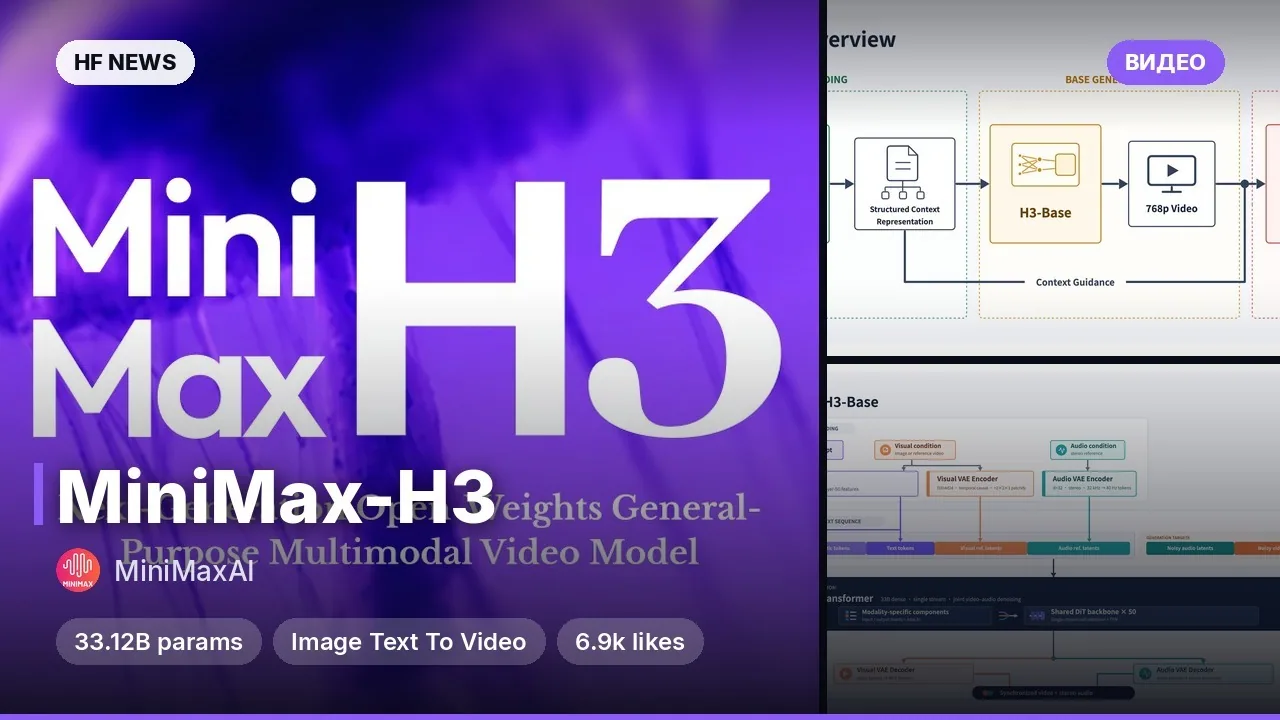
- 2MiniMax-H3
Video · 7.2K
- 3Flat Color - Style
Images · 6.2K
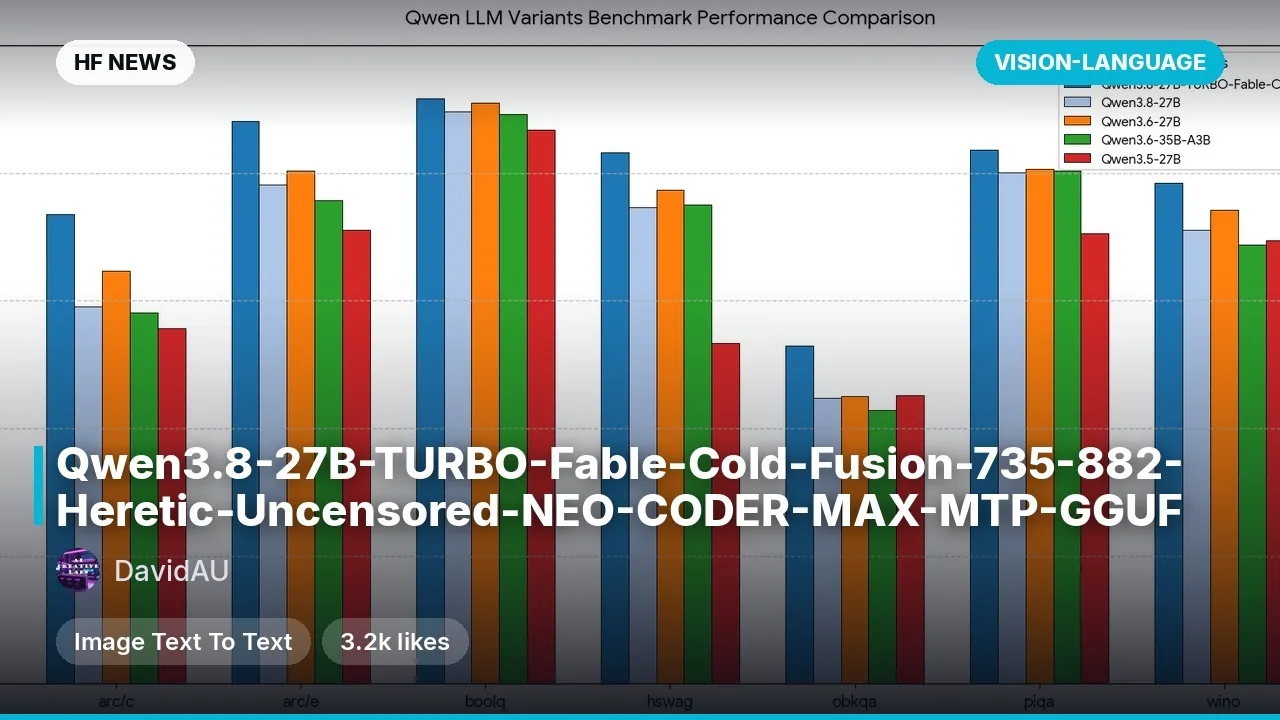
- 4Qwen3.8-27B-TURBO-Fable-Cold-Fusion-735-882-Heretic-Uncensored-NEO-CODER-MAX-MTP-GGUF
Computer vision · 3.5K
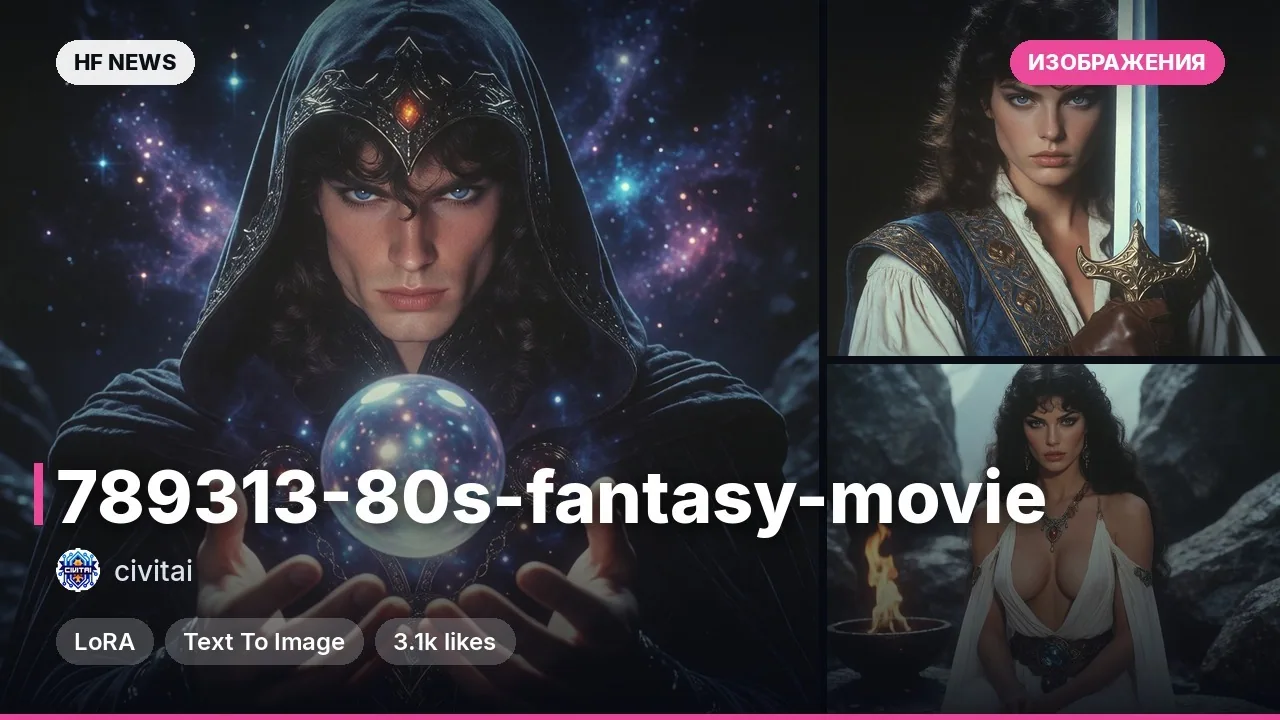
- 580s Fantasy Movie
Images · 3.1K
 18+
Popular tags
- #finetune1751
- #LLM1345
- #models1296
- #LoRA1072
- #Qwen930
- #images585
- #txt2img482
- #robotics467
- #VLM349
- #audio270
- #NSFW207
- #Krea193
- #video186
- #MiniMax_H3170
- #ComfyUI159
- #Gemma139
- #turbo129
- #MOSS_Image123
- #ASR107
- #TTS99