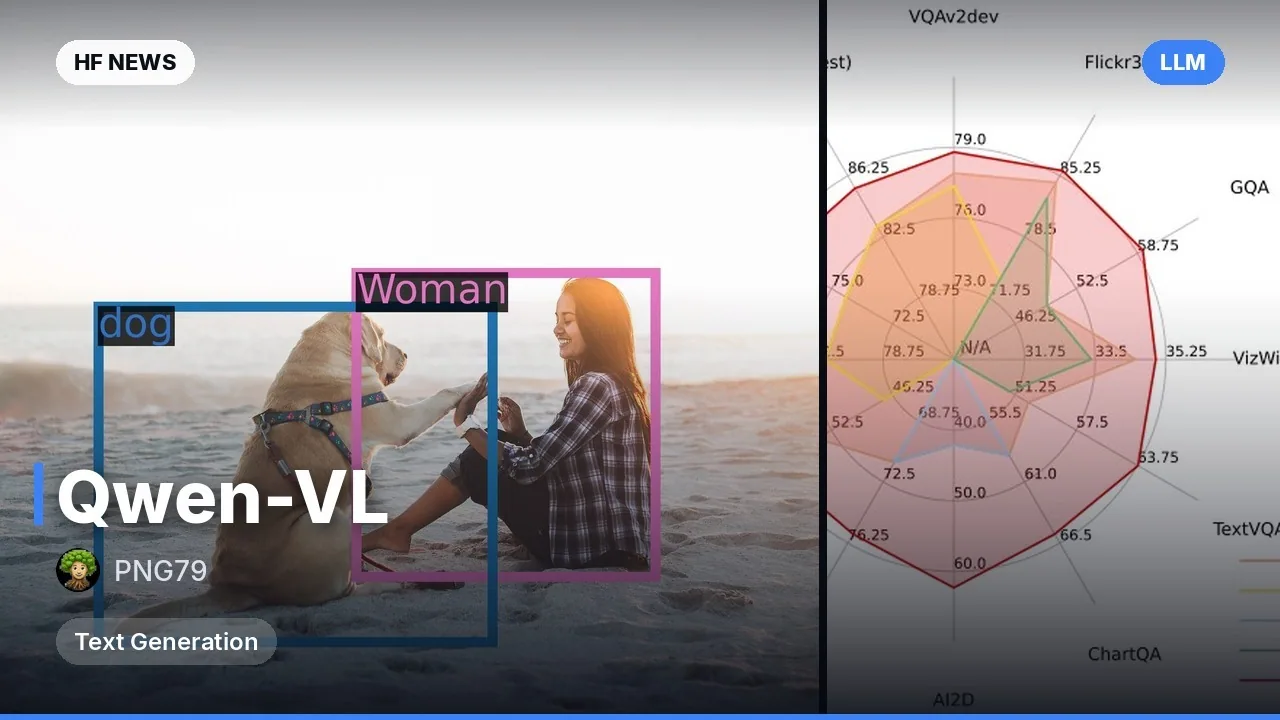
Qwen-VL: Multimodal AI model for text and object recognition in images
Qwen-VL by Alibaba Cloud is a large vision-language model (LVLM) capable of taking images, text, and bounding boxes as input, and returning text and object coordinates.
The latest large language models and their fine-tunes.
Qwen-VL by Alibaba Cloud is a large vision-language model (LVLM) capable of taking images, text, and bounding boxes as input, and returning text and object coordinates.
LoRA adapter for emotion analysis with JSON output
Developed by the ArrowLabs team, AresXLG1 is part of the Ares family and delivers strong results on the Open SLM Leaderboard (the top benchmark for compact models). It was trained on 50 billion tokens (text fragments for analysis) using carefully filtered datasets, including DCLM, UltraFineWeb L3…
The google/gemma-4-E2B-it model has been fine-tuned using LoRA to answer research questions based on provided scientific abstracts. It outputs a structured JSON response containing a label (yes, no, or maybe), a brief summary, and the sentence numbers it relies on.
Kaze-4.7B-A530M-MIT is an experimental foundational language model trained from scratch by developer Kineyo under the MIT license. The model uses a Sparse Mixture-of-Experts architecture, meaning that out of a total size of about 4.72B parameters, only about 528M parameters are activated per token.
Grace-G1-350M-Instruct is an instruction-tuned version of a 377M parameter model by BranchingNLP, built for conversations, small talk, and simple tasks in English and Italian.
The GoodJob model (110M parameters, built on bert-base-uncased) is designed to analyze posts from Twitter/X or LinkedIn. It features two classification heads: the first determines the post type (ranging from specialized AI/ML job listings to non-work posts), and the second evaluates author…
NeyroLearn
@neyrolearn
New models from Hugging Face every morning: video, images, LoRAs and LLMs with examples and links.
Most liked on Hugging Face this week
Images · 8.4K
 18+
Video · 7.2K
Images · 6.2K
Computer vision · 3.5K
Images · 3.1K
 18+