New LLMs · page 2
The latest large language models and their fine-tunes.
MN-12B-Mag-Mell-R1 Uncensored
fully unlocked version of the creative language model
maintenance-work-order-triage-5M
An ultra-lightweight model for maintenance work order triage
LLaDA2.2-mini-Thinking: A reasoning model for block-diffusion MoE
This model is an upgraded version of LLaDA2.2-mini (a 16B block-diffusion MoE ( Mixture of Experts ) with 1.4B active parameters), fine-tuned to reason inside … tags before generating a response or calling tools. The base model answers immediately without reasoning in text.
tiny-aya-fire-esa-grpo-success-only
research model for agent safety evaluation
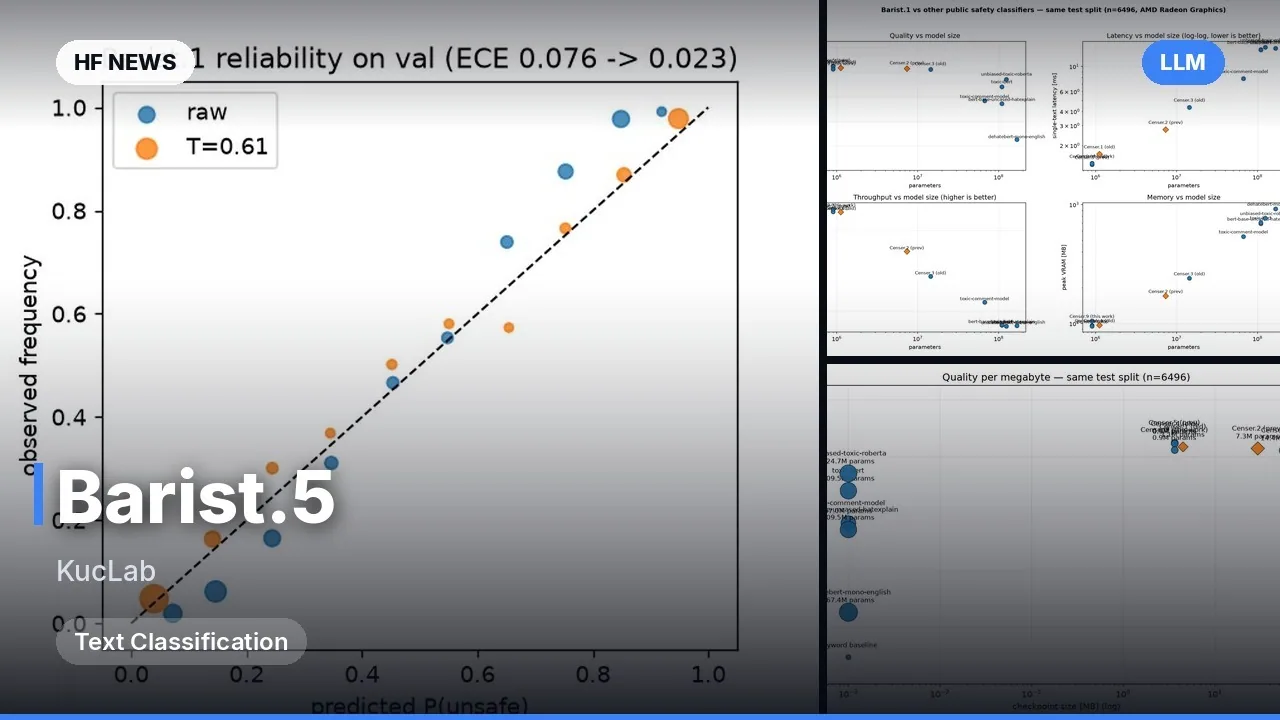
Muse-Prompt-Shield-1-25M: A compact shield for protecting LLMs from prompt injections
Muse-Prompt-Shield-1-25M is a fast multilingual classifier (24.8M parameters) trained to detect dangerous instructions in user queries and third-party data. The model categorizes incoming text into three groups: benign, indirect prompt injection via third-party data, and jailbreaks.
Air-Quality SLM v3
a compact language model for environmental monitoring
safetypulse-h2-lora-alpacalist
A set of LoRA checkpoints for studying safety drift
modernjev-8k - fast bank request classifier for 8192 tokens
The modernjev-8k model by developer vennyvirtuoso handles the text-classification task, identifying user intent across 77 categories in financial and banking requests (such as transfer fee issues, card activation, or card blocking).
MC7ever/lfm3-omni-dualhead
A single dual-head architecture for fast decisions and generation
Amaara Code Flash v8: Specialized coding and tool-calling agent
The Amaara Code Flash v8 model is designed for programming automation and code tasks as a tool-calling coding agent. It is built on the GLM-4.7-Flash base model (31.2B total / ~3B active MoE — Mixture of Experts architecture where only a portion of parameters is activated per token).
Qwen3-8B-InWeight-FPGA-WSP
compiling a dialectical automaton into model weights
LevelUp AI: QLoRA adapter for Llama-3.2-3B-Instruct
A new QLoRA adapter (QLoRA: an efficient low-precision fine-tuning method for large language models) equips the base Llama-3.2-3B-Instruct model with seven distinct coaching personas for a gamified self-development app.
NeyroLearn
@neyrolearn
New models from Hugging Face every morning: video, images, LoRAs and LLMs with examples and links.
- Posts
- 1336
- Tags
- 59
Trending
Most liked on Hugging Face this week
- 1Add Micro Details
Images · 8.4K
 18+
- 2MiniMax-H3
Video · 7.2K
- 3Flat Color - Style
Images · 6.2K
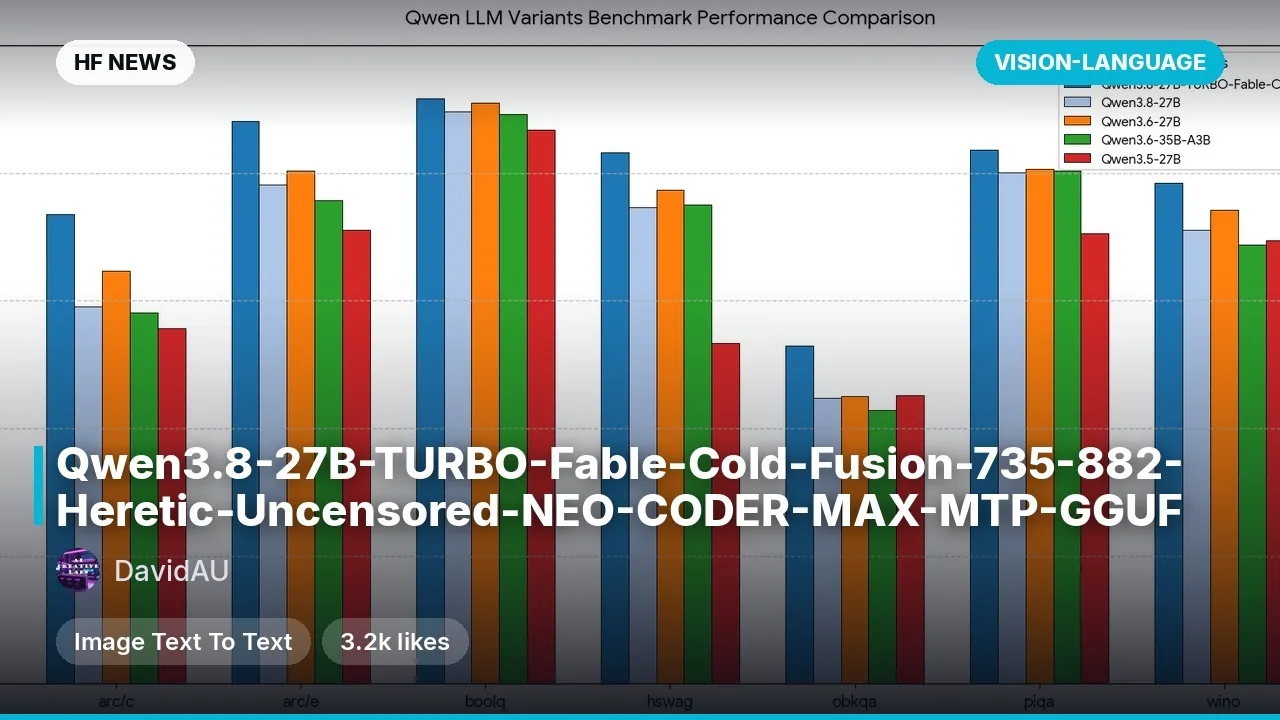
- 4Qwen3.8-27B-TURBO-Fable-Cold-Fusion-735-882-Heretic-Uncensored-NEO-CODER-MAX-MTP-GGUF
Computer vision · 3.5K
- 580s Fantasy Movie
Images · 3.1K
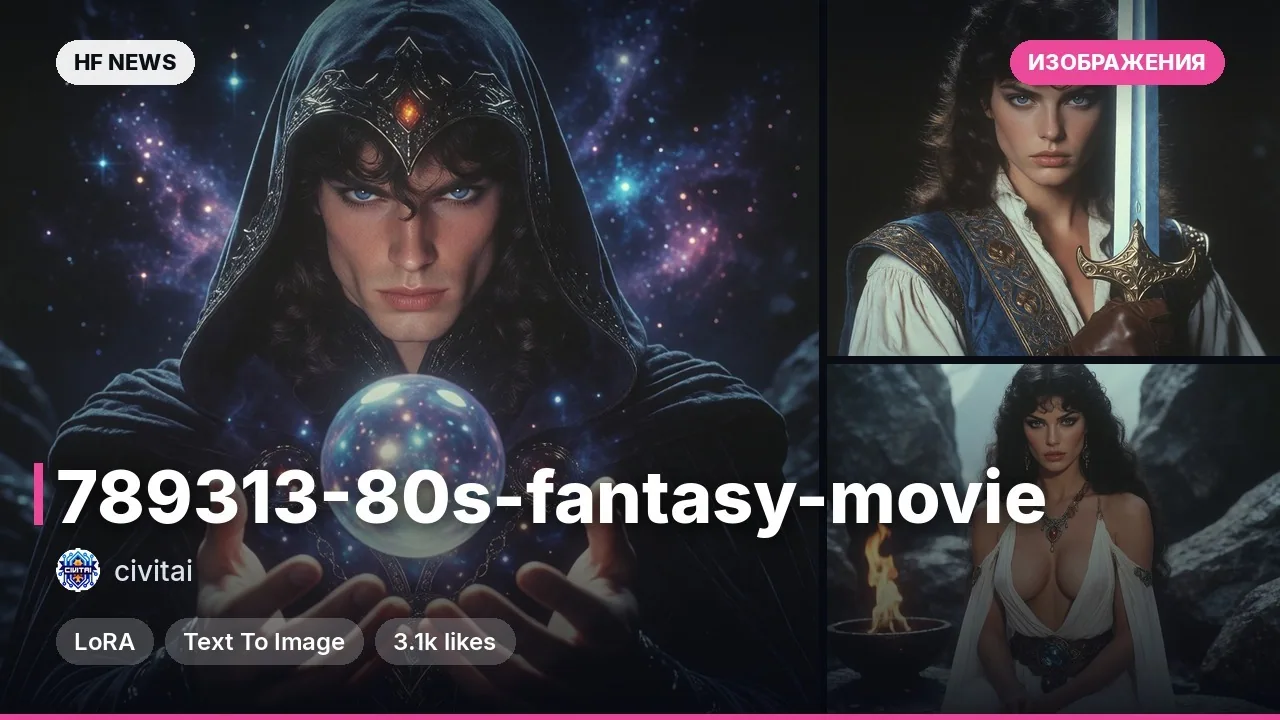 18+
Popular tags
- #finetune1741
- #LLM1336
- #models1292
- #LoRA1070
- #Qwen924
- #images584
- #txt2img481
- #robotics467
- #VLM346
- #audio270
- #NSFW207
- #Krea193
- #video183
- #MiniMax_H3168
- #ComfyUI157
- #Gemma139
- #turbo128
- #MOSS_Image123
- #ASR107
- #TTS99