#finetune · page 2
1741 posts
hal-rock/qwen3-4b-maze-grpo-fft
Qwen3-4B model fine-tuned with reinforcement learning in a maze
Kanata-S1-3B: A compact coding and agentic LLM based on Granite 4.1
The K-Ai (Kortex AI) team has released a compact 3.4-billion-parameter language model fine-tuned for coding and AI agent tasks. Built on top of ibm-granite/granite-4.1-3b-base, it was fine-tuned using SFT (supervised fine-tuning on examples) with QLoRA (quantized adapter for memory efficiency…
 18+
MN-12B-Mag-Mell-R1 Uncensored
fully unlocked version of the creative language model
AzurLane GPT-SoVITS V5dev: 902 character voices for voice generation
A set of weights for the popular GPT-SoVITS V5dev speech synthesis system, trained on Japanese and Chinese voice lines from the game Azur Lane. The model covers 902 ship characters and lets you generate speech in Russian, Chinese, or Japanese using a short audio clip (3 to 10 seconds) as a…
maintenance-work-order-triage-5M
An ultra-lightweight model for maintenance work order triage
AzurLane GPT-SoVITS v2ProPlus: 902 Character Voice Pack
This set of weights for GPT-SoVITS (a voice cloning and speech synthesis system) is trained to voice 902 ships and TB assistants from Azur Lane in Japanese and Chinese. A total of 933 voice presets are available, including alternative versions and different localization options.
LLaDA2.2-mini-Thinking: A reasoning model for block-diffusion MoE
This model is an upgraded version of LLaDA2.2-mini (a 16B block-diffusion MoE ( Mixture of Experts ) with 1.4B active parameters), fine-tuned to reason inside … tags before generating a response or calling tools. The base model answers immediately without reasoning in text.
tiny-aya-fire-esa-grpo-success-only
research model for agent safety evaluation
GeoReader-Qwen2.5-VL-3B-MindCube: A Vision-Language Model for Geospatial Analysis
The GeoReader-Qwen2.5-VL-3B-MindCube model is a full checkpoint (set of weights) based on Qwen2.5-VL-3B-Instruct, fine-tuned for spatial perception and geometry tasks. The architecture combines a vision-language model (VLM), a frozen geometric reader, an adapter, and a gate.
NeyroLearn
@neyrolearn
New models from Hugging Face every morning: video, images, LoRAs and LLMs with examples and links.
- Posts
- 1741
- Tags
- 59
Trending
Most liked on Hugging Face this week
- 1Add Micro Details
Images · 8.4K
 18+
- 2MiniMax-H3
Video · 7.2K
- 3Flat Color - Style
Images · 6.2K
- 4Qwen3.8-27B-TURBO-Fable-Cold-Fusion-735-882-Heretic-Uncensored-NEO-CODER-MAX-MTP-GGUF
Computer vision · 3.5K
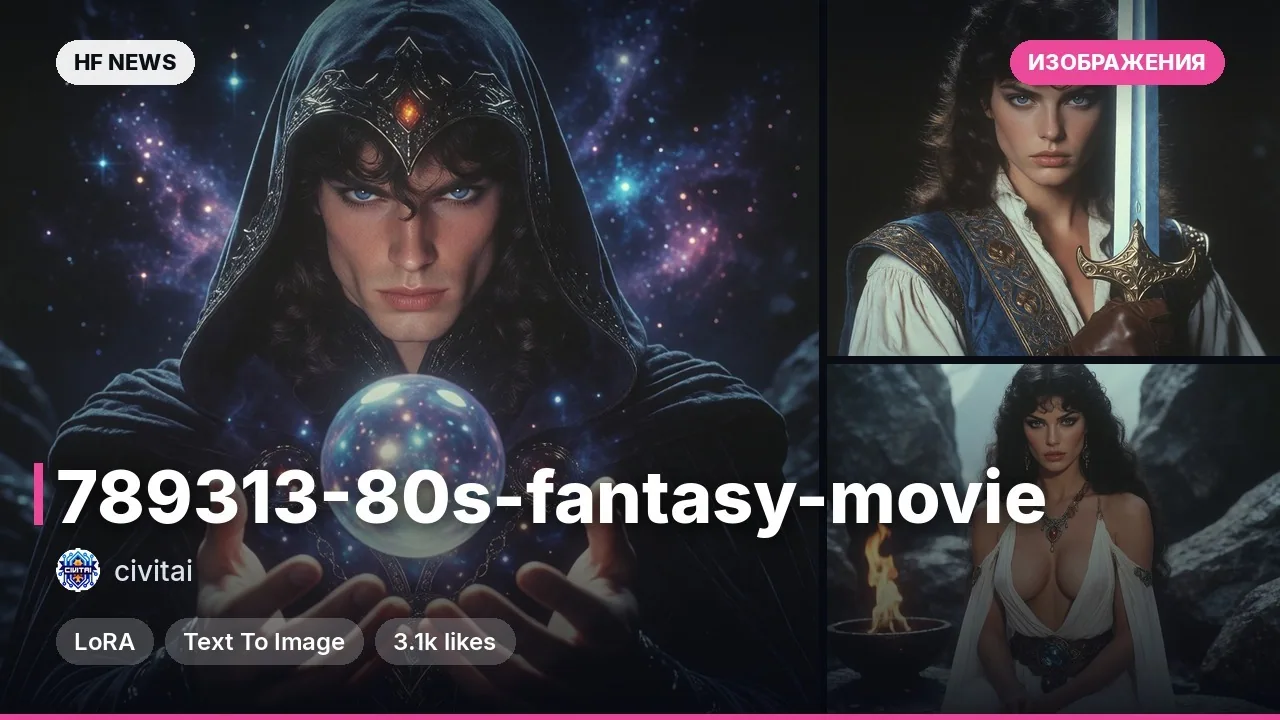
- 580s Fantasy Movie
Images · 3.1K
 18+
Popular tags
- #finetune1741
- #LLM1336
- #models1291
- #LoRA1070
- #Qwen924
- #images584
- #txt2img481
- #robotics467
- #VLM346
- #audio269
- #NSFW207
- #Krea193
- #video183
- #MiniMax_H3168
- #ComfyUI157
- #Gemma139
- #turbo128
- #MOSS_Image123
- #ASR107
- #TTS98