VLA_Samer_08.11.2026_400eps_policy_XVLA
a VLA policy for the UR5 robot
2 min readupdated
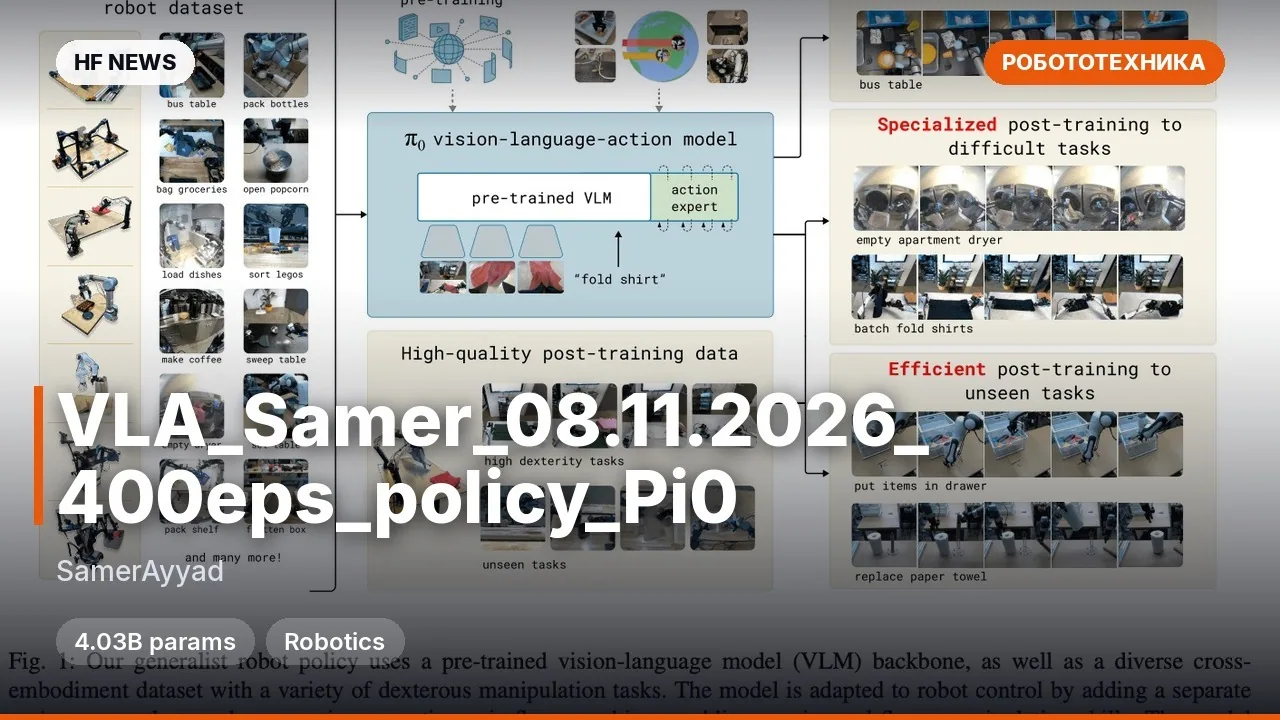
This model is a VLA policy (Vision-Language-Action — an AI model that links vision, text instructions, and physical actions) built to control a ur5 industrial robotic arm. Trained on the 0.88B-parameter lerobot/xvla-base model using the LeRobot framework, it handles a specific pick-and-place task: using a vacuum gripper to pick up a CPU and place it into a box. The X-VLA architecture uses flow-matching alongside learnable Soft Prompts (trainable prompt vectors) that adapt a single unified model to a specific robot's sensor setup and action space. It is aimed at robotics engineers and researchers working with Universal Robots manipulators.
Key features
- Built on
lerobot/xvla-base(0.88B parameters) using LeRobot version 0.6.2. - Takes feeds from three cameras (two 256×256 streams and one 224×224 stream) plus an 8-dimensional robot state vector.
- Outputs a 7-dimensional action vector to control picking and placing operations.
- Trained on a 400-episode dataset (259,635 frames recorded at 30 FPS).
What you can do
- Deploy the pre-trained policy on a real UR5 arm equipped with a vacuum gripper to sort and pack CPUs.
- Use the weights and configuration as a reference baseline when training custom X-VLA policies in LeRobot.
Example
lerobot-rollout \
  --strategy.type=base \
  --robot.type=ur5 \
  --robot.port= \
  --policy.path=SamerAyyad/VLA_Samer_08.11.2026_400eps_policy_XVLA \
  --task="Pick up the CPU with the suction gripper and place it in the box" \
  --duration=60
Read more
DetailsTraining: 20,000 steps, batch size 8, xvla-adamw optimizer, learning rate 0.0001.
Real-world robot evaluation results are not yet listed on the model card.
License: Apache-2.0.


Comments