Qwen3.8-27B-opencode-adapted-GGUF
a code model quantized for llama.cpp
2 min readupdated
This model is a quantized GGUF version of the fine-tuned Qwen/Qwen3.8-27B model, optimized for coding and terminal tasks. It was created by merging the base model with a LoRA adapter trained using reinforcement learning in the Harbor and OpenEnv environments. The model supports built-in Multi-Token Prediction (MTP) to speed up generation during local execution. It is useful for developers and engineers running a local AI coding assistant.
Key features
- Ready-to-use GGUF format: Models are quantized to run via llama.cpp without needing separate LoRA attachments.
- Multi-Token Prediction (MTP): Built-in multi-token prediction heads accelerate generation without a separate draft model.
- Various quantization options: Versions ranging from compact Q4 to maximum Q8 are available.
- Code specialization: Trained for engineering tasks and terminal workflows.
What you can do
- Local execution: Deploy the model in applications and utilities supporting llama.cpp and the GGUF format.
- Software development: Use it for code generation, debugging, and automating terminal tasks.
- Multimodal tasks: Attach a separate projection file
mmproj-bf16.ggufto work with images.
Example
Download the main weights file for your desired quantization (for example, Q4_K_M) alongside the mmproj-bf16.gguf projection file, then run them through a compatible llama.cpp engine for coding work.
Read more
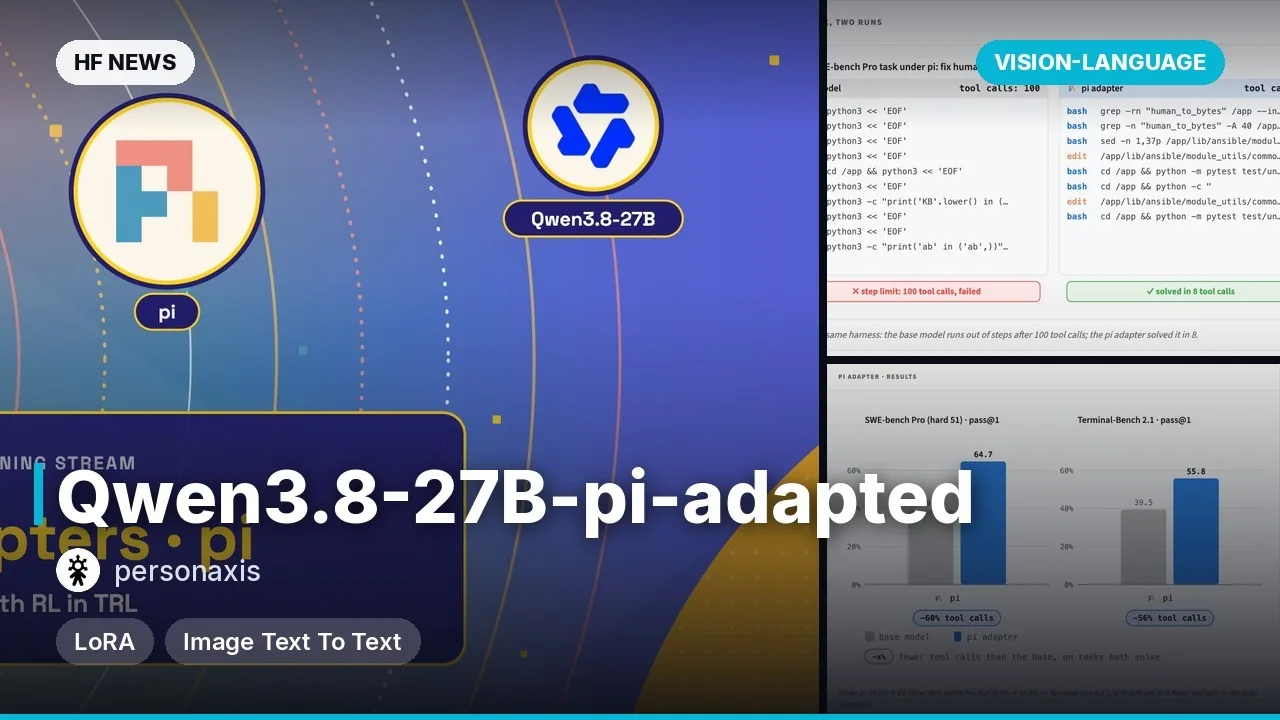
DetailsAdapter benchmarks: SWE-bench Pro (hard 51) — 51.0% (compared to 35.3% for base), Terminal-Bench 2.1 — 52.4% (compared to 46.4%).
File sizes: From 15.8 GB to 29 GB for the main weights and 931 MB for mmproj.
Features: Contains built-in MTP tensors to speed up inference.


Comments