Skip to content
Robotics

leap_t4a_groot_n17_40k

политика для роборуки LEAP с тактильным восприятием

2 min readupdated

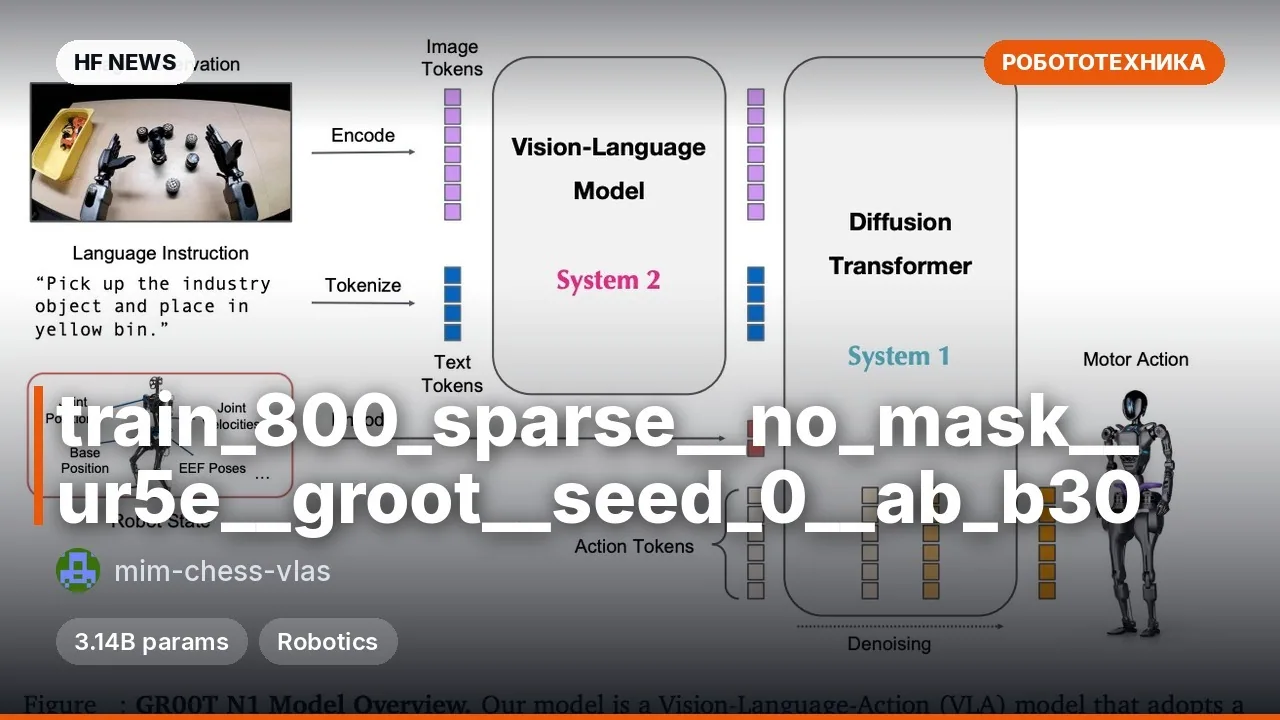
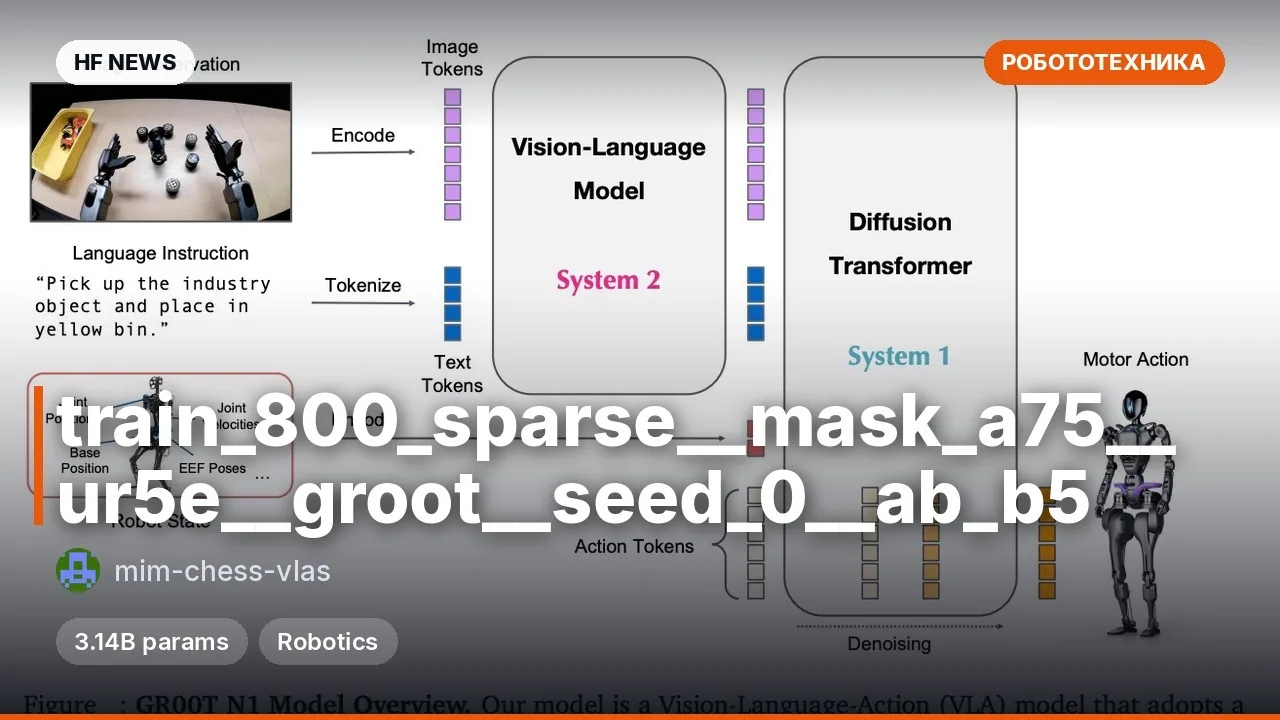
Модель представляет собой файнтюн (дообучение) nvidia/GR00T-N1.7-3B на 3,14 млрд параметров, созданный пользователем mfincato в библиотеке LeRobot. Она управляет манипулятором Panda с четырёхпалой кистью LEAP hand для задачи захвата объекта и перекладывания его в тарелку. Главная особенность — данные с трёх тактильных датчиков на кончиках пальцев (GelSight Mini, Daimon и DIGIT) подаются не как картинки, а в виде числового вектора состояния после кодировщика touch-for-all и сжатия методом PCA (метод главных компонент). Пригодится исследователям робототехники, работающим с тактильной обратной связью и VLA-политиками (моделями «зрение-язык-действие»).

Ключевые особенности

  • Тактильные данные как вектор состояния: сигналы с большого, указательного и среднего пальцев кодируются через touch-for-all v26 e32 и сжимаются общим PCA до 96 значений (по 32 на палец, сохраняя 93,5% дисперсии).
  • Мультимодальный вход и диффузионное действие: принимает кадр с левой камеры сцены (480×640, приводится к 256×256 с полями) и вектор состояния из 125 параметров, выдавая последовательность из 40 шагов действия (выполняются первые 5 на частоте 10 Гц).
  • Разделение окружений при запуске: тактильный кодировщик (transformers 4.42, numpy < 2) конфликтует с окружением GR00T (transformers 5.x), поэтому запускается отдельным процессом и передаёт 96 значений в основной процесс политики.
  • Финальный чекпоинт обучения: версия на 40 000 шагов (в репозитории автора также доступна версия на 10 000 шагов с более низким eval loss для сравнения на реальном роботе).

Что можно сделать

  • Запустить управление связкой манипулятора Panda и кисти LEAP hand с тактильными сенсорами для захвата и перекладывания предметов.
  • Сравнить на реальном оборудовании поведение чекпоинта на 40 000 шагов с версией mfincato/leap_t4a_groot_n17_10k, чтобы оценить влияние переобучения на точность захвата.
  • Использовать скрипты deploy_tactile.py и пайплайн кодирования из репозитория как референс для интеграции разнородных тактильных датчиков в политики LeRobot.

Пример

from lerobot.policies.factory import make_pre_post_processors
from lerobot.policies.groot.modeling_groot import GrootPolicy

repo = "mfincato/leap_t4a_groot_n17_40k"
policy = GrootPolicy.from_pretrained(repo).to("cuda").eval()
pre, post = make_pre_post_processors(policy.config, pretrained_path=repo)
policy.reset()
action = post(policy.select_action(pre(obs)))
ПодробнееМетрики: held-out eval loss на 40 000 шагах составил 0.210 (у чекпоинта на 10 000 шагов — 0.105; минимум 0.095 фиксировался на 4 000 шаге).
Обучение: 40 000 шагов на 1 × A100 80 GB (batch 32, AdamW lr 1e-4, bf16) на датасете HOUJC128/leap_jc_one_clean (90 эпизодов для обучения, 11 для валидации); заморожены LLM и vision tower, обучались проектор, диффузионная голова действий и VL layer norm.
Ограничения: требует специального форка LeoGori/lerobot с двумя патчами (включая 256×256 letterbox), а датчик DIGIT на среднем пальце имеет смещение в покое около 0,7 Н.

Discuss Telegram 0 6

Will it run?

Runs in F32

Fits without quantisation.

  • F32weights 12 GB · ready files13 GB
  • BF16weights 5.9 GB6.9 GB
  • FP8 / INT8recommendedweights 2.9 GB3.7 GB
  • 4-bitweights 1.6 GB2.3 GB

Tip: go 8-bit.FP8 / INT8 is within about a percent of full precision in quality, takes half the memory and runs faster on RTX 40/50 and H100. Full precision only pays off for fine-tuning.

What to get for this model

Massed ComputeOpen Massed Compute

Your own GPU: FP8 / INT8 — from RTX 2060 · F32 — from RTX 5080

Massed Compute hourly prices, November 2026. The discounted price applies with the coupon at checkout.

Estimate: weights plus working memory. Long videos, high resolutions and long contexts need more.

Run it on Massed Compute

The script downloads the model to the rented machine. How to run it is in the model card.

  1. 1. Rent a machine with a fitting GPU

    Open Massed Compute
  2. 2. Paste the script into the machine's terminal

    Connect over SSH (the Massed Compute panel shows the command) or open a terminal on the machine's desktop.

    HF_TOKEN / CIVITAI_TOKENThe script starts with token lines: paste yours between the quotes. The Hugging Face token is for gated models, the Civitai one for Civitai models.

    # mfincato/leap_t4a_groot_n17_40k
    mkdir -p ~/models
    curl -LsSf https://astral.sh/uv/install.sh | sh
    source "$HOME/.local/bin/env"
    uv tool install "huggingface_hub[cli]"
    hf download mfincato/leap_t4a_groot_n17_40k --local-dir ~/models/leap_t4a_groot_n17_40k
    # The model is in ~/models. How to run it is in the model card (link above).
    Add more LoRAs to leap_t4a_groot_n17_40k
  3. 3. Use it

    The model is in ~/models. How to run it is in the model card (link above).

Stop the machine in the panel when you are done: it bills by the minute while it runs.

How to speed it up

Picked for this model type. Choose your hardware above to see what fits you exactly.

  • FlashAttention 44.0.0b40from November 18, 2026new release

    fastest exact attention on B200

    Kernels for Blackwell (beta). Exact attention without quantisation — fine for everything, LLMs included.

    How to enable: pip install flash-attn-4; vLLM and SGLang pick it up themselves.

    Earlier generations (2)
    • FlashAttention 3 — The Hopper (H100/H200) version with FP8.
    • FlashAttention 2 — The standard for RTX 30/40/50 and A100: exact attention without the memory cost of long contexts.
  • torch.compile2.15.0from October 28, 2026new release

    10–30% for free

    Compiles the model for your GPU. Slower first run, faster afterwards.

    How to enable: model = torch.compile(model); in ComfyUI the TorchCompileModel node.

Model family

New posts about versions of GR00T-N1.7-3B (quants, finetunes, LoRAs) will show up under the bell.

Quantised versions 3All on Hugging Face
Fine-tunes 12All on Hugging Face
LoRAs and adapters 1All on Hugging Face

About the model

mfincato/leap_t4a_groot_n17_40k
Author
mfincato
Category
Robotics
Released
Posted

On NeyroLearn

Hugging Face

60

Ask AI about this model

Answered by Gemini 4 · the chat is kept only in this tab

Comments