Skip to content
Computer vision

Qwen3.8-27B-Coder390-EXL3-3.85bpw

27B кодер с vision и контекстом 262k на одной RTX 3090

2 min readupdated

Квантизованная версия мультимодальной модели Qwen3.8-27B-Coder390 в формате EXL3 (сжатие весов для видеокарт NVIDIA, в среднем 3.85 бита на параметр) от исследователей из Автономного университета Барселоны (JRamirez-UAB). Она решает задачи программирования, рассуждений и анализа изображений, позволяя развернуть тяжёлую модель на одной потребительской карте с 24 ГБ видеопамяти. В отличие от многих обрезанных сборок, здесь сохранены модуль зрения (6 бит) и MTP (Multi-Token Prediction — спекулятивное декодирование на 3 токена вперёд для ускорения генерации). Пригодится разработчикам, которые запускают локальных ИИ-агентов и ассистентов для кода.

Ключевые особенности

  • Точное сжатие 3.85 bpw: основные веса сжаты до 3.85 бита, голова модели — до 5 бит, модуль зрения — до 6 бит, а эмбеддинги токенов — до 8 бит.
  • Полный контекст 262 144 токена: модель умещается в 24 ГБ VRAM вместе с KV-кэшем (k8v4) и поддержкой до 8 изображений на запрос.
  • Высокая скорость с MTP: спекулятивное декодирование на 3 токена даёт 86 ток/с в один поток и до 248 ток/с при 4 параллельных запросах на RTX 3090.
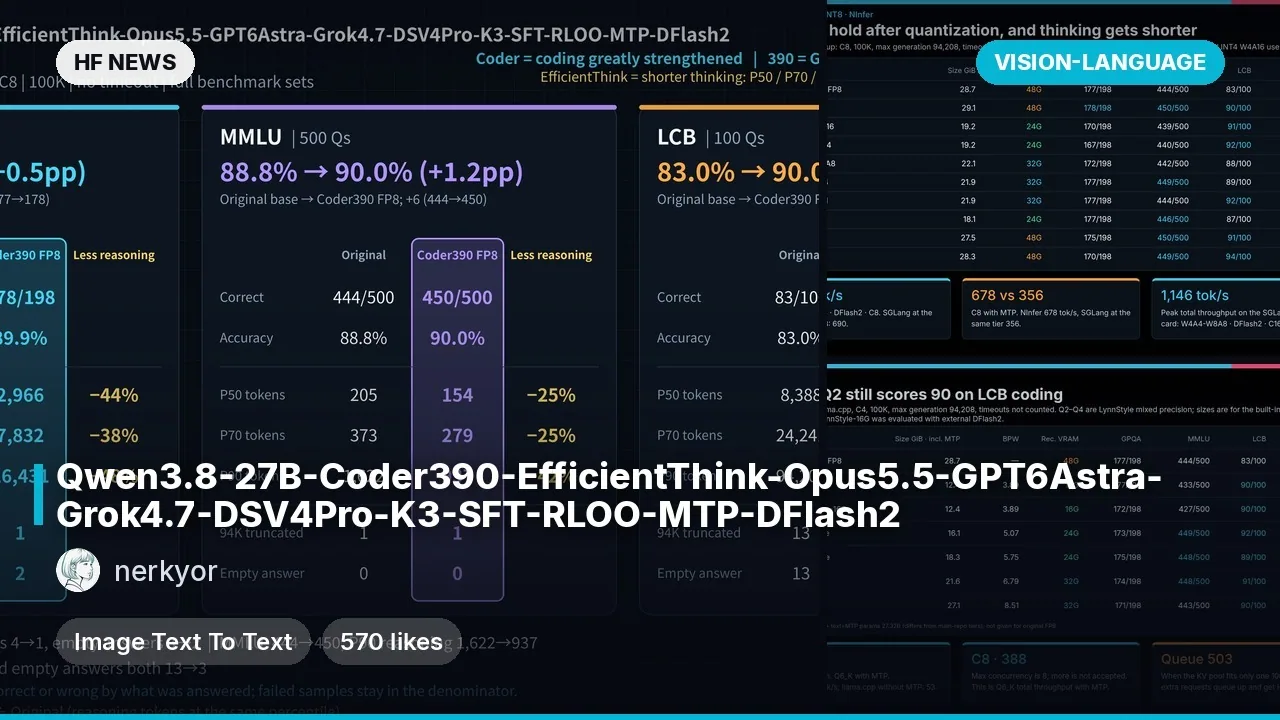
  • Минимальная потеря качества: расхождение (KLD) с оригинальной BF16-версией составляет всего 0.0089 на реальных агентских сценариях opencode.

Что можно сделать

  • Запустить локального ИИ-агента для кода: подключить модель через vLLM к инструментам вроде opencode — в тестах она безошибочно отработала 30/30 вызовов инструментов и 10/10 агентских задач.
  • Анализировать скриншоты и схемы с кодом: благодаря сохранённому vision-модулю можно отправлять модели интерфейсы, диаграммы и длинные репозитории до 262k токенов.

Пример

vllm serve JRamirez-UAB/Qwen3.8-27B-Coder390-EXL3-3.85bpw \
  --served-model-name coder390 --max-model-len 262144 \
  --kv-cache-dtype k8v4_per_token_head --kv-cache-memory-bytes 8500000000 \
  --limit-mm-per-prompt '{"image": 8}' --reasoning-parser qwen3 \
  --enable-auto-tool-choice --tool-call-parser qwen3_coder \
  --speculative-config '{"method":"mtp","num_speculative_tokens":3}'
ПодробнееЖелезо и софт: протестировано на одной RTX 3090 (24 ГБ VRAM, CUDA sm_86) в vLLM 0.33 с плагином quantpack 0.1.5.
Бенчмарки на RTX 3090: Vision 15/15, Reasoning 18/18, поиск в контексте (Needle) на 64k/128k/241k — 8/8, игровые задачи по коду — 42/48 баллов.
Важное ограничение: при низкой температуре модель склонна зацикливаться в рассуждениях (при T=0.6 зациклились 8 из 30 промптов, при T=1.0 — 0 из 30). Используйте штатный конфиг: temperature=1.0, top_p=0.95, top_k=20.


Discuss Telegram 0 12

Will it run?

Runs in I16

Fits without quantisation.

  • I16weights 14 GB · ready files15 GB
  • FP8 / INT8recommendedweights 7.4 GB8.6 GB
  • 4-bitweights 4.2 GB5.1 GB

Tip: go 8-bit.FP8 / INT8 is within about a percent of full precision in quality, takes half the memory and runs faster on RTX 40/50 and H100. Full precision only pays off for fine-tuning.

What to get for this model

Massed ComputeOpen Massed Compute

Your own GPU: FP8 / INT8 — from RTX 3080 · I16 — from RTX 5080

Massed Compute hourly prices, November 2026. The discounted price applies with the coupon at checkout.

Estimate: weights plus working memory. Long videos, high resolutions and long contexts need more.

Run it on Massed Compute

The script downloads the model to the rented machine. How to run it is in the model card.

  1. 1. Rent a machine with a fitting GPU

    Open Massed Compute
  2. 2. Paste the script into the machine's terminal

    Connect over SSH (the Massed Compute panel shows the command) or open a terminal on the machine's desktop.

    HF_TOKEN / CIVITAI_TOKENThe script starts with token lines: paste yours between the quotes. The Hugging Face token is for gated models, the Civitai one for Civitai models.

    # JRamirez-UAB/Qwen3.8-27B-Coder390-EXL3-3.85bpw
    mkdir -p ~/models
    curl -LsSf https://astral.sh/uv/install.sh | sh
    source "$HOME/.local/bin/env"
    uv tool install "huggingface_hub[cli]"
    hf download JRamirez-UAB/Qwen3.8-27B-Coder390-EXL3-3.85bpw --local-dir ~/models/Qwen3.8-27B-Coder390-EXL3-3.85bpw
    # The model is in ~/models. How to run it is in the model card (link above).
  3. 3. Use it

    The model is in ~/models. How to run it is in the model card (link above).

Stop the machine in the panel when you are done: it bills by the minute while it runs.

How to speed it up

Picked for this model type. Choose your hardware above to see what fits you exactly.

  • FlashAttention 44.0.0b40from November 18, 2026new release

    fastest exact attention on B200

    Kernels for Blackwell (beta). Exact attention without quantisation — fine for everything, LLMs included.

    How to enable: pip install flash-attn-4; vLLM and SGLang pick it up themselves.

    Earlier generations (2)
    • FlashAttention 3 — The Hopper (H100/H200) version with FP8.
    • FlashAttention 2 — The standard for RTX 30/40/50 and A100: exact attention without the memory cost of long contexts.
  • torch.compile2.15.0from October 28, 2026new release

    10–30% for free

    Compiles the model for your GPU. Slower first run, faster afterwards.

    How to enable: model = torch.compile(model); in ComfyUI the TorchCompileModel node.

Model family

  1. Qwen3.8-27B-EfficientThink-Uncensored-K3-Opus5-Grok4.6-GPT5.6Sol-SFT-SimPO-DFlash2family root
  2. Qwen3.8-27B-Coder390-EfficientThink-Opus5.5-GPT6Astra-Grok4.7-DSV4Pro-K3-SFT-RLOO-MTP-DFlash2
  3. Qwen3.8-27B-Coder390-EXL3-3.85bpw

New posts about versions of Qwen3.8-27B-EfficientThink-Uncensored-K3-Opus5-Grok4.6-GPT5.6Sol-SFT-SimPO-DFlash2 (quants, finetunes, LoRAs) will show up under the bell.

Quantised versions 8All on Hugging Face
Fine-tunes 2All on Hugging Face

About the model

JRamirez-UAB/Qwen3.8-27B-Coder390-EXL3-3.85bpw
Author
JRamirez-UAB
Category
Computer vision
Released
Posted

On NeyroLearn

Hugging Face

120

Ask AI about this model

Answered by Gemini 4 · the chat is kept only in this tab

Comments