Skip to content
Images

Nix Comic [Multiple Styles]

flexible comic-style LoRA

1 min read

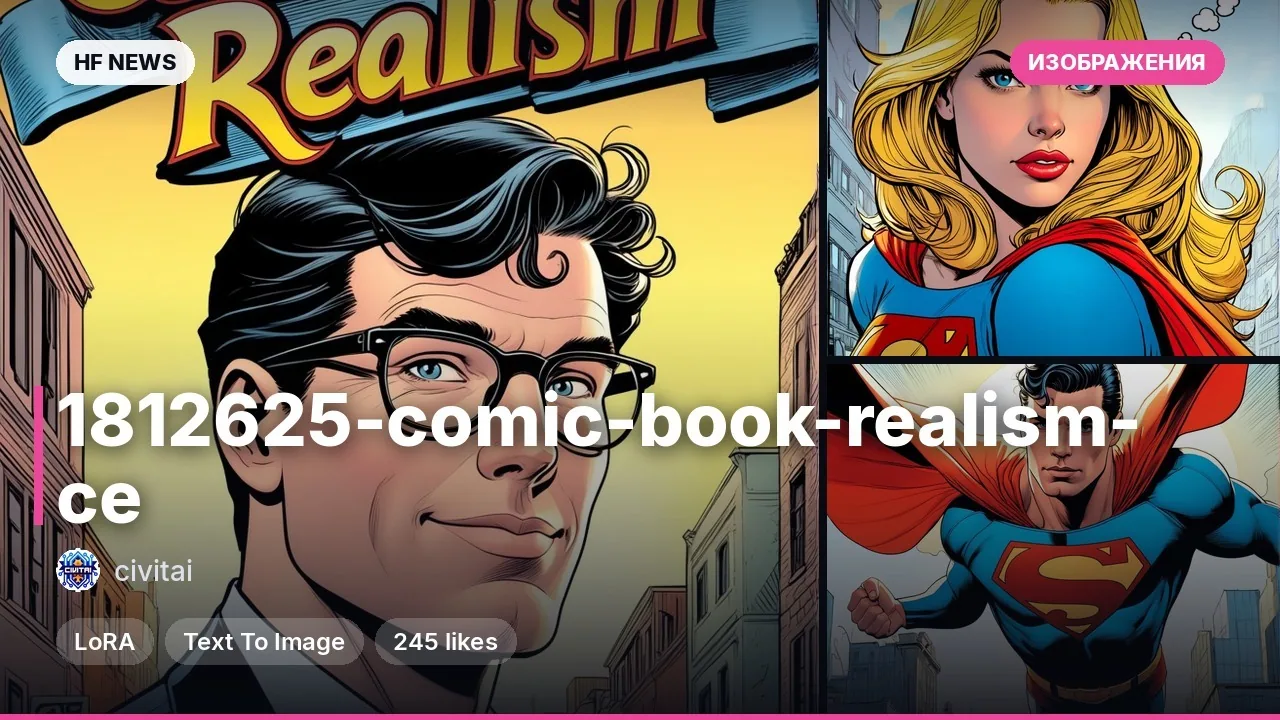
This LoRA for the MOSS Image model blends 90s Disney animation aesthetics with 2000s Marvel comics, creating a flexible base for illustration generation. It is designed with a focus on character diversity (avoiding same-face or identical body types) and pairs cleanly with other LoRAs and text prompts. The recommended weight is 0.7–0.85, leaving plenty of room for style mixing. It is a great fit for artists, comic creators, and fans of stylized graphics.

Key features

  • Blends classic Disney animation and retro Marvel comic styles.
  • Supports anatomical diversity and varied facial features without "same-face" syndrome.
  • Combines easily with other LoRAs and style prompts.
  • Flexible strength tuning (0.7–0.85 recommended).

What you can do

  • Generate 90s cartoon-style illustrations with signature linework and textures.
  • Blend this LoRA with character or artist adapters (such as European comic styles).
  • Create concept art for your own comics or animation projects.

Example

Run the LoRA with the MOSS Image base model at a weight of 0.7–0.85. Example prompt: «A dynamic scene of a hero in 1990s comic book style, flat colors, distinct line work, detailed background».

Read moreDetails
Base model: MOSS Image
Type: LORA
Tags: comic, style, illustration
Highlights: variations include European comic and retro animation styles

Examples
Discuss 320 4.8K

Will it run?

Runs in FP8 / INT8

Full precision does not fit, a quantised version does: quality barely changes down to 8 bits, more noticeably at 4 bits.

  • BF16weights 25 GB · ready files29 GB
  • FP8 / INT8recommendedweights 12 GB15 GB
  • 4-bitweights 6.9 GB9.1 GB

Tip: go 8-bit.FP8 / INT8 is within about a percent of full precision in quality, takes half the memory and runs faster on RTX 40/50 and H100. Full precision only pays off for fine-tuning.

What to get for this model

Massed ComputeOpen Massed Compute

Your own GPU: FP8 / INT8 — from RTX 5080 · BF16 — from RTX 5090

Massed Compute hourly prices, November 2026. The discounted price applies with the coupon at checkout.

This is a LoRA: counted together with its base model Krea-2-Raw.

Estimate: weights plus working memory. Long videos, high resolutions and long contexts need more.

Run it on Massed Compute

A ready script for the machine we advise above: paste it and the model downloads and starts.

  1. 1. Rent A30

    $0.26 an hour with the coupon. Pick the Ubuntu image when you create the machine.

    Open Massed Compute
  2. 2. Paste the script into the machine's terminal

    Connect over SSH (the Massed Compute panel shows the command) or open a terminal on the machine's desktop.

    HF_TOKEN / CIVITAI_TOKENThe script starts with token lines: paste yours between the quotes. The Hugging Face token is for gated models, the Civitai one for Civitai models.

    #!/usr/bin/env bash
    # 2836231-nix-comic-multiple-styles
    set -e
    # ===== Tokens: paste yours between the quotes =====
    export CIVITAI_TOKEN=""   # civitai.com/user/account → API Keys, for Civitai LoRAs
    # ==========================================
    # NVIDIA driver: CUDA 13 needs 580+. If older or missing, the current nvidia-open is installed (keep yours: KEEP_DRIVER=1)
    DRV=$(nvidia-smi --query-gpu=driver_version --format=csv,noheader 2>/dev/null | head -1 | cut -d. -f1)
    case "$DRV" in ""|*[!0-9]*) DRV=0 ;; esac
    if [ "$DRV" -lt 580 ] && [ -z "${KEEP_DRIVER:-}" ]; then
      . /etc/os-release && \
      curl -fsSLO "https://developer.download.nvidia.com/compute/cuda/repos/ubuntu${VERSION_ID//./}/x86_64/cuda-keyring_1.1-1_all.deb" && \
      sudo dpkg -i cuda-keyring_1.1-1_all.deb && rm -f cuda-keyring_1.1-1_all.deb && \
      sudo apt-get update && \
      sudo DEBIAN_FRONTEND=noninteractive apt-get install -y nvidia-open || \
      { echo "Could not install the NVIDIA driver: see the error above. To keep the current one, run with KEEP_DRIVER=1."; exit 1; }
      echo "NVIDIA driver updated. Reboot the machine (sudo reboot) and run this same script again."
      exit 0
    fi
    curl -LsSf https://astral.sh/uv/install.sh | sh
    source "$HOME/.local/bin/env"
    # CUDA 13+ → int8_convrot (Comfy-Org's advice), else fp8_scaled
    CU=$(nvidia-smi | grep -oP 'CUDA Version: \K[0-9]+' || echo 12)
    [ "$CU" -ge 13 ] && TORCH=cu130 || TORCH=cu128
    [ -d ~/ComfyUI ] || git clone https://github.com/comfyanonymous/ComfyUI ~/ComfyUI
    cd ~/ComfyUI
    uv venv --python 3.12 --allow-existing && source .venv/bin/activate
    uv pip install torch torchvision torchaudio --index-url https://download.pytorch.org/whl/$TORCH
    uv pip install -r requirements.txt "huggingface_hub[cli]"
    civitai() {  # civitai <model id> <folder>: the newest version of a Civitai model
      vid=$(curl -fsSL "https://civitai.com/api/v1/models/$1" | python3 -c 'import json,sys;print(json.load(sys.stdin)["modelVersions"][0]["id"])')
      (cd "$2" && curl -fL -OJ -H "Authorization: Bearer $CIVITAI_TOKEN" "https://civitai.com/api/download/models/$vid")
    }
    # Base files: Krea 2, 8-bit
    if [ "$CU" -ge 13 ]; then
      hf download Comfy-Org/Krea-2 diffusion_models/krea2_raw_int8_convrot.safetensors text_encoders/qwen3vl_4b_int8_convrot.safetensors vae/qwen_image_vae.safetensors --local-dir models
    else
      hf download Comfy-Org/Krea-2 diffusion_models/krea2_raw_fp8_scaled.safetensors text_encoders/qwen3vl_4b_fp8_scaled.safetensors vae/qwen_image_vae.safetensors --local-dir models
    fi
    # LoRAs (1)
    civitai 2836231 models/loras
    # Start ComfyUI. From your computer: ssh -L 8188:localhost:8188 user@IP, then http://localhost:8188
    python main.py --listen 127.0.0.1 --port 8188
    Add more LoRAs to Krea-2-Raw
  3. 3. Use it

    From your computer: ssh -L 8188:localhost:8188 user@machine-IP, then open http://localhost:8188. Or open that address in the browser on the machine's desktop. The model's workflow is usually in its Hugging Face card.

Stop the machine in the panel when you are done: it bills by the minute while it runs.

How to speed it up

Picked for this model type. Choose your hardware above to see what fits you exactly.

  • SageAttention 3v2.2.0from October 28, 2025

    even faster on RTX 50 / Blackwell

    FP4 attention for Blackwell. Faster than SageAttention 2, but the authors suggest v2 when accuracy matters.

    How to enable: Build from the sageattention3_blackwell folder of the repo; in ComfyUI via KJNodes.

    Earlier generations (2)
    • SageAttention 2++ — Quantised (INT8/FP8) attention with no visible quality loss. The main speed-up for image and video generation.
    • SageAttention 1 — First version: INT8 for Q·K. Still works, but 2++ is faster and more accurate.
  • FlashAttention 44.0.0b40from November 18, 2026new release

    fastest exact attention on B200

    Kernels for Blackwell (beta). Exact attention without quantisation — fine for everything, LLMs included.

    How to enable: pip install flash-attn-4; vLLM and SGLang pick it up themselves.

    Earlier generations (3)
    • FlashAttention 3 — The Hopper (H100/H200) version with FP8.
    • FlashAttention 2 — The standard for RTX 30/40/50 and A100: exact attention without the memory cost of long contexts.
    • xFormers — The older way to speed up attention, works almost everywhere. Sage or Flash are faster where available.
  • cache-dit (DBCache)v1.5.6from November 20, 2026new release

    1.5–3× at nearly the same quality

    Reuses block outputs between diffusion steps. Supports most DiT models.

    How to enable: pip install cache-dit; one line cache_dit.enable_cache(pipe) for diffusers.

    Earlier generations (2)
    • MagCache — Skips steps by magnitude of change. More accurate than TeaCache, no calibration.
    • TeaCache — The first popular diffusion step cache. Works, newer methods are more accurate.
  • Nunchaku (SVDQuant 4-bit)v1.2.1from January 25, 2026

    ≈3× faster and 3.5× less memory

    4-bit versions of popular image models with almost no quality loss (FP4 on RTX 50).

    How to enable: Ready weights for supported models; in ComfyUI use ComfyUI-nunchaku.

  • torch.compile2.15.0from October 28, 2026new release

    10–30% for free

    Compiles the model for your GPU. Slower first run, faster afterwards.

    How to enable: model = torch.compile(model); in ComfyUI the TorchCompileModel node.

Model family

Requires the base model

krea/Krea-2-Raw

This model is a LoRA / adapter. Download the base model first, then load this one on top.

New posts about versions of Krea-2-Raw (quants, finetunes, LoRAs) will show up under the bell.

Quantised versions 12All on Hugging Face
Fine-tunes 12All on Hugging Face
LoRAs and adapters 12All on Hugging Face

About the model

civitai/2836231-nix-comic-multiple-styles
Author
xFennec777
Category
Images
Released
Posted

On NeyroLearn

Civitai

4.8K320

Ask AI about this model

Answered by Gemini 4 · the chat is kept only in this tab

Comments