Article
MoE: Accuracy jumps from 59.7% to 71.3% via repeated expert reselection
An independent developer testing a looped Transformer with MoE found that reselecting experts at every iteration boosts multi-step math problem solving.
prisstik Founder@prissetik
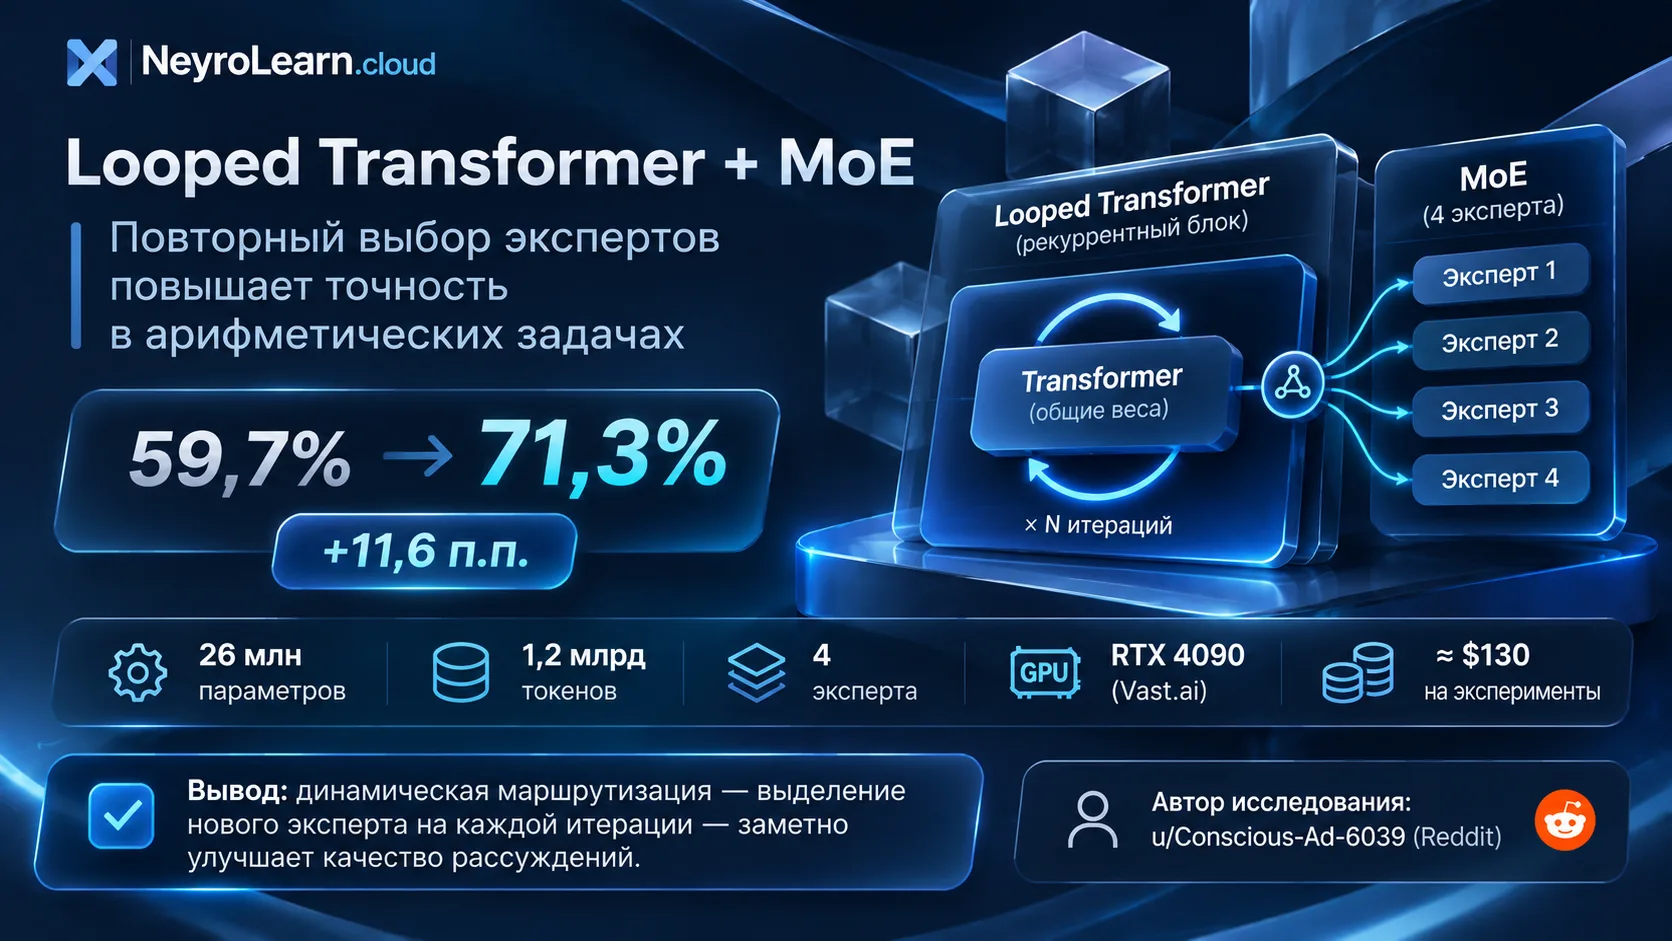
Looped Transformer + MoE: accuracy jumps from 59.7% to 71.3% via repeated expert reselection
An independent developer replicated the NVIDIA Dory architecture on a model with just 26M parameters and uncovered an interesting quirk: reselecting MoE experts at each iteration noticeably improves performance on multi-step math tasks.
In a standard Transformer, each layer has its own weights. In a looped Transformer, the same block is reused multiple times, allowing the model to progressively refine its internal representations without increasing the parameter count.
The experiment's author added four small MoE experts into a shared recurrent block and compared two approaches:
- Fixed routing: An expert is chosen on the first iteration and used across all subsequent ones.
- Dynamic routing: The model reselects an expert for each token before every iteration.
Results
| Approach / Metric | Value |
|---|---|
| Fixed expert selection | 59.7% accuracy |
| Repeated expert selection | 71.3% accuracy |
| Improvement | 11.6 percentage points |
| Test loss in both cases | 1.711 |
The improvement held across all three runs using different seeds. The biggest performance gap showed up in complex arithmetic problems requiring multiple sequential operations.
Experiment Parameters
- 26M parameters.
- 1.2B training tokens per model.
- 4 MoE experts.
- PyTorch and rented RTX 4090 GPUs via Vast.ai.
- Around $130 spent on the described series of experiments.
Another interesting finding: the "one-loop tax"
The author also replicated an effect where a model trained with only a single iteration essentially matched the recurrent model running three iterations, while consuming roughly three times less compute during inference.
This indicates that extra loops do not always provide a genuine gain: part of the improvement may simply compensate for the quirks of training with a variable number of iterations.
Why it matters
The experiment suggests that applying different experts sequentially can be more effective than a fixed choice across all computation stages. This presents a potentially interesting direction for compact reasoning models where making efficient use of a limited parameter count is crucial.
However, these results were obtained on small models and a limited set of tasks. Confirming the approach's effectiveness on large LLMs will require further research.
Author of the study: [u/Conscious-Ad-6039 (Reddit)](https://www.reddit.com/r/learnmachinelearning/comments/1xv9asm/reselecting
Source code, tests, and experiment logs: https://github.com/Davidooff/Spidory
Architecture foundation: NVIDIA Dory.
#LLM #MoE #Transformer #NVIDIA #PyTorch #Reasoning #Research
Comments